
How NVIDIA and SK Hynix Are Building the Next Generation AI Factory
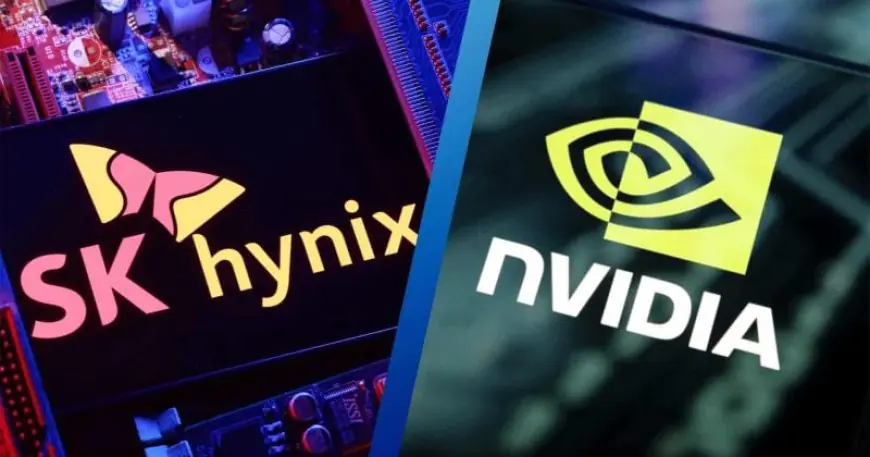
NVIDIA and SK Hynix have announced a multiyear strategic partnership to develop advanced memory technologies specifically designed for AI factories. The collaboration targets one of the biggest bottlenecks in large-scale AI deployment: the speed and efficiency of data movement between chips and memory.

A Partnership Born From AI's Hungriest Problem
There is a dirty secret inside every impressive AI demo you have seen. The model might be brilliant, but the bottleneck is almost never the compute. It is the memory. Getting data in and out of chips fast enough to keep those expensive GPUs fed has become the single biggest headache for anyone building AI infrastructure at scale. That is precisely why NVIDIA and SK Hynix just announced a multiyear partnership to reinvent how memory works inside what they call "AI factories."
What Exactly Is an AI Factory
The term "AI factory" sounds like marketing buzz, but it actually describes something real and growing. Unlike traditional data centers that store and serve files, AI factories are purpose-built facilities where massive models are trained and deployed continuously. Think of them less like libraries and more like power plants. They ingest raw data, process it through thousands of GPUs working in parallel, and output intelligence—predictions, classifications, generated content. And just like a power plant, an AI factory is only as good as its transmission lines. Those transmission lines are memory.
Why Memory Became the Bottleneck
For years, the industry focused on making GPUs faster. And NVIDIA delivered. But a funny thing happened on the way to artificial general intelligence. The chips got so fast that they started spending most of their time waiting. Waiting for data to arrive from memory. Waiting to write results back. This "memory wall" has become the limiting factor for both training large models and running inference at scale. SK Hynix, the South Korean memory giant, has been quietly leading the charge on High Bandwidth Memory or HBM—a stacked architecture that moves data much faster than traditional DRAM. This new partnership locks them in as NVIDIA's strategic ally for the foreseeable future.
The Key Technologies Driving This Deal
The collaboration focuses on several advanced memory technologies designed specifically for AI workloads. According to industry sources and the official announcement from SK Hynix, here are the core areas of development:
- Next-generation HBM (HBM4e) – Stacked memory with significantly higher bandwidth and lower power consumption than current generations
- Processing-in-memory (PIM) – Integrating basic compute capabilities directly into memory chips to reduce data movement
- Custom memory controllers – Designing memory specifically for NVIDIA's GPU architectures rather than using off-the-shelf components
- Thermal and power optimization – Solving the heat problems that arise when you push massive amounts of data through tightly packed chips
- Scalable memory fabrics – Allowing multiple GPUs to share a unified memory pool across an entire AI factory floor
What This Means for AI Deployment Costs
If you have been following the economics of AI, you already know that inference costs have been falling but training costs remain astronomical. A big reason is memory inefficiency. GPUs sit idle while waiting for data, but you still pay for the hardware. By improving memory bandwidth and reducing latency, NVIDIA and SK Hynix could slash the total cost of ownership for AI factories. Some analysts estimate that next-generation HBM could reduce training times for massive models by thirty to forty percent. That is not just a technical win. That is a business model shift.
As noted in a recent Reuters analysis of the partnership announcement, the timing is no accident. Competitors including AMD and Intel are racing to develop their own AI memory solutions, often in partnership with other manufacturers. By locking in SK Hynix exclusively for key technologies, NVIDIA is trying to widen its moat just as the rest of the industry catches up on raw compute.
The Geopolitical Angle You Cannot Ignore
SK Hynix is South Korean. NVIDIA is American. Both companies operate under export controls that restrict what can be sold to certain markets, particularly China. This partnership is not just technical. It is also strategic. By deepening ties between US and South Korean supply chains, both companies are insulating themselves from disruption. If something happens to Taiwan-based production, this alliance provides a partial hedge. It also aligns with the US government's push for "friend-shoring" critical semiconductor capabilities.
That said, China is not standing still. Domestic memory makers like CXMT and YMTC are racing to develop their own HBM alternatives. And Chinese AI labs have become remarkably efficient at squeezing performance out of less advanced hardware. The NVIDIA-SK Hynix partnership is partly a response to that pressure—a way to stay two generations ahead rather than one.
When Will We See Real Products
The partnership is multiyear, meaning you should not expect shipping products next quarter. HBM4e is expected to enter production in late 2027, with early samples going to NVIDIA for validation. Full-scale deployment in AI factories will likely happen in 2028. That timeline feels slow in AI terms, but memory development cannot be rushed. The margins for error are microscopic, and a single design flaw can wipe out billions in value.
The Bottom Line for Enterprises
If you are an enterprise building or renting AI infrastructure, this partnership is good news. More efficient memory means either faster models for the same price or the same speed for less money. Either way, your cost per token or per training run is heading down. The real winners will be the cloud providers—AWS, Google Cloud, Azure—who can pack more effective compute into each rack. But even smaller players using rented capacity will feel the benefit.
The bigger story here is that the AI hardware race is maturing. For the past two years, everyone focused on GPU flops. Now the battle is shifting to the less glamorous but equally critical world of memory, interconnects, and system architecture. NVIDIA and SK Hynix just placed a very large bet that the next frontier of AI infrastructure is not more compute—it is getting that compute the data it needs, faster and cheaper than anyone else. If they are right, your AI applications are about to get a whole lot snappier.